
How to Edit Talking Head Videos Without the Robotic Feel: The Full Workflow From Rough Cut to Review
A complete talking-head editing workflow in the order the work happens — selecting takes, cutting silence without flattening pacing, smoothing jump cuts, captions, B-roll, and platform formats — with what an AI editing agent can draft and what you should review yourself.

The talking-head format hides a paradox. It looks like the easiest thing to edit — one camera, one speaker, no scenes to synchronize — and it is reliably the format where automated editing goes wrong. The failure is rarely a sloppy cut; it is an over-edited one. Every pause gets stripped, every repetition removed, every gap compressed, until the speaker stops sounding like a person thinking and starts sounding like a person reading. Creators call the result the "robotic feel," and it damages the one thing a talking-head video actually sells: the sense of a real human working through an idea in front of you.
The cause is usually a category error. Most tutorials and most tools treat editing as a checklist problem — remove silence, delete retakes, add captions — when talking-head editing is a judgment problem. A pause can be dead air or it can be emphasis forming; a repetition can be a mistake or it can be a take being selected. Software can execute either decision instantly; deciding which decision is the right one is the part that shapes the video. This guide is organized around that split: what the mechanical pass can absorb, what your judgment has to keep, and in what order the work should happen.
The mechanical half is not trivial, either. Editors have a rule of thumb for it, the Rule of 60: every finished minute of video costs roughly an hour of culling takes, cutting silence, syncing captions, and exporting variants. It is folklore rather than measurement, and your ratio may well be kinder, but anyone who has finished a twelve-minute tutorial at 2 AM recognizes the shape of the curve. The realistic goal of a better workflow is not deleting that hour — it is moving the janitorial work ahead of your review, instead of letting it compete with your judgment for the same evening.
Here is the map and its borders. This article owns the end-to-end talking-head workflow — footage, silence, pacing, jump cuts, captions, B-roll, formats, and the final review — for commentary, tutorials, explainers, and video essays. Three adjacent topics get a summary where they intersect the workflow and a link to their own guides: automatic B-roll sourcing, caption generation and cleanup economics, and tool-by-tool comparisons. And where an editing agent appears in the steps below, it means Sparki, the product we build — we are one implementation of the agentic pattern, not a neutral judge of it.
What Makes Talking-Head Editing Different
In most formats, the picture carries the story. In a talking-head video, the speaker's thinking process is the content, and the speaker is the visual anchor. Every cut therefore lands on two channels at once: it removes material from the argument, and it changes how the person delivering that argument feels on screen. The same cut can be right in a vlog and wrong in a tutorial, which is why no universal checklist survives contact with real footage.
Three distinctions carry most of the practical weight. Dead air is not a pause: dead air is a gap with no function, while a pause is often where emphasis lands or the next thought forms. Repetition is not automatically a mistake: speakers circle a sentence to get the delivery right, and the fix is selecting the best take, not deleting all of them or none of them. And pacing is not speed: an edit that removes every breath reads as breathless, and breathlessness reads as insincerity. Automation executes the first half of each distinction reliably; the craft is recognizing which half you are looking at.
That boundary — what hands over well and what should stay with you — has a systematic treatment in what AI video editors can and can't automate. Talking-head is the format where automation helps most, because speech-led footage is predictable and the cuts have clear triggers. It is also the format where skipping review is most audible, because there is nothing else on screen to hide a misjudgment behind.
The Workflow, in the Order the Work Happens
- Organize the footage and select takes
- Cut silence and fillers without flattening the speech
- Do one pacing pass for rhythm
- Hide the jump cuts
- Add captions
- Layer B-roll sparingly
- Adapt the frame for each platform
- Review the draft
Step 1: Organize the Footage Before You Cut
The first job is the one nobody misses until they skip it: knowing what you actually have. A talking-head recording is often an hour of material for ten minutes of video, and the useful parts hide inside retakes, false starts, throat-clearing, and the sentence you said three ways because the third one finally landed. Editors call the pass that sorts this the assembly cut, and it is the least creative, most fatiguing work in the format — every decision is small, and none of them can be skipped.
It is also the step an editing agent absorbs best. On material it has analyzed — how well AI editors read footage, and where that reading breaks, is covered in how AI editors understand your footage — it can propose which take looks cleanest, flag the false starts, and outline the sections worth keeping. A proposal, not a verdict: the judgment to keep is take selection on delivery-dependent lines. If a joke lands better in the second take than in the technically cleaner third one, no analysis replaces your ear. Confirm takes before any fine cutting, because every later decision inherits them.
Step 2: Cut Silence and Fillers Without Flattening the Speech
Threshold-based silence removal is the classic robot factory. A decibel threshold cannot tell a thinking pause from dead air, so aggressive settings strip-mine both, and the speaker ends up sounding like they were denied oxygen mid-sentence. The opposite failure is just as common: conservative settings leave the recording untouched and the video drags. The fix is not a better number on the threshold; it is a different criterion — cut by function, not by volume.
In practice that means three moves. Fillers and dead air go: the ums, the uhs, the gaps where nothing is happening and nothing is about to. Micro-pauses stay: the half-second before a key point, the breath between an argument and its payoff, the beats that signal "I am thinking" rather than "I am buffering." And gaps tighten rather than vanish: the distance between thoughts shrinks so the video keeps moving, while the human rhythm inside each thought survives. An agent applies this consistently, on clip seven as on clip one; whether it landed is exactly what your review pass checks.
A microphone and audio waveform displayed on a laptop during a talking head video recording, commonly used to illustrate voice editing, pacing, and silence removal.
Step 3: Do One Pacing Pass for Rhythm
After cleanup, watch the cut once — only for cadence. Not content, not visuals: cadence. Does the argument accelerate where it should? Does the ending land or trail off? Are the intentional pauses still intentional, or did the cleanup pass nick the edges of a comedic beat? Content that leans on timing — jokes, rhetorical questions, escalation — is where automated pacing fails most visibly, and where one deliberate watch earns the most. If you lay music under the cut, this is also the pass where its level and ducking get judged by ear.
The honest boundary is that pacing judgment does not hand over. An agent can tighten gaps and place emphasis; it cannot feel that a section drags by two seconds or that a reveal arrived one sentence early. Creators who skip this pass get videos that are technically clean and somehow lifeless — assembled rather than edited. One focused watch is usually enough to catch it.
Step 4: Hide the Jump Cuts
Once time is removed, the picture jumps: head position snaps between takes, and the eye registers every seam. Raw jump cuts read as amateur; the professional fix is a subtle punch-in — a small scale change on the clip after the cut that gives the frame a reason to look different. The working guideline is a scale change of around ten percent: enough to register as a visual reset, small enough that most viewers never consciously notice the edit. Push much past it and the manipulation becomes the thing viewers watch.
Where the punch-ins land matters more than how big they are. A zoom on a timer feels mechanical within thirty seconds; a zoom at the moment the argument shifts — the turn from problem to solution, the delivery of the key number — feels intentional, because it follows the emphasis rather than decorating the timeline. An agent places these at semantic turning points in the draft; you check in review that the turns it picked are the turns you meant.
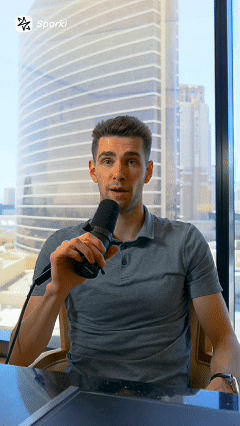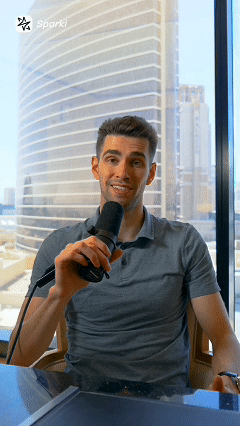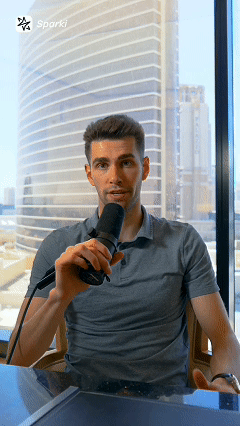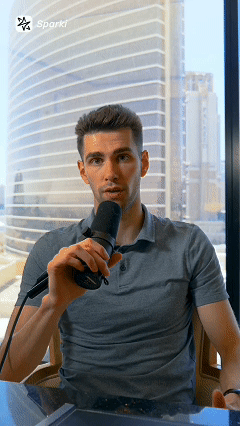
Demonstration of context-aware zoom applied at narrative turning points to visually mask jump cuts without breaking viewer trust or attention.
Step 5: Add Captions
Captions decide whether the video works on mute, and mute viewing is common enough that platforms treat captions as a default rather than an extra. For YouTube talking-head, an editable SRT keeps later revisions cheap, because every trim after the first pass shifts caption timing underneath; for Shorts, Reels, and TikTok cuts from the same master, burned-in captions are usually the pragmatic choice. The full decision tree — burned-in versus file export, and when native tooling is enough — is laid out in the caption workflow comparison.
The part worth being precise about: speech-to-text alignment on a single clear speaker drafts well, and errors cluster around proper nouns, technical terms, and accents. Treat the first caption pass as a draft to verify, not a fact to assume — a silently swapped word is worse than an obvious error because it looks correct. Alignment accuracy and language coverage vary by tool and shift as models update, so check current figures on the product side rather than trusting any number printed in an article.
Step 6: Layer B-Roll Sparingly
The instinct after a clean cut is to "add visuals," and this is where talking-head videos quietly lose credibility. Generative video makes it trivial to fill every gap with attractive, generic footage, and audiences have developed a sharp radar for it — creators call the result AI slop. The test for B-roll in a talking-head video is not "is this a good clip" but "does this visual come from the same reality as the story being told." When you describe a real storefront closing, a generated storefront feels unanchored even when it looks beautiful.
The stronger source is your own footage. An agent that has watched your material can match the moment you mention an economic downturn to the drone shot you actually filmed — grounded, on-brand, and free of licensing questions. The full mechanics of automatic B-roll, the generative and curation paths, their failure modes, and the review loop around them have their own guide in how to auto-add B-roll to talking-head videos.
Step 7: Adapt the Frame for Each Platform
A 16:9 master usually needs 9:16 offspring. The naive hard crop takes the center of the frame and hopes the speaker lives there; subject-aware reframing does better, tracking the speaker and keeping them positioned as the vertical version is built. The honest phrasing of the boundary: this reduces framing misses, it does not make them impossible, and it is not outpainting — nothing invents the pixels outside your original frame. Glance at face position and any on-screen text near the edges before export, and for the full geometry of crop, blur-background, and reframe choices, see how to resize video for Shorts, Reels, and TikTok.
The Review Pass
An automated draft deserves the same two-layer check a junior editor's cut would get. The first layer verifies the mechanics — the things the tool should have handled:
- Takes: the selected takes are the ones you would have picked, especially on delivery-dependent lines
- Cleanup: dead air and fillers gone without the cadence turning breathless
- Jump cuts: punch-ins subtle, and placed at turns you actually meant
- Captions: synced, with names and technical terms correct
- Framing: speaker and on-screen text safe in every export format
The second layer is shorter, because it is the part nothing automates:
- Does the pacing breathe where the argument needs air?
- Does the video deliver the idea the way you would say it out loud?
- Is this the version you would put your name on?
If the first layer holds, the second takes one focused watch. That is the realistic version of escaping the Rule of 60: the mechanical hour does not vanish — it happens before your review, consistently, instead of eating the evening your judgment needed.
Where This Workflow Lives
Talking-head editing is served by every generation of tool, differently. A timeline NLE gives frame-level control and charges you in operations; the Rule of 60 is partly a description of timeline work. Transcript editors and rough-cut accelerators such as Descript and Gling automate the cleanup layer well and are compared head-to-head in Descript vs Gling. The agentic pattern — brief in plain language, receive a draft, refine in conversation — is the newest entry, and the five-type map of the market with the evidence behind it is in the AI video editor guide. If your format is commentary specifically and the pain is the timeline itself, the case for chat-to-edit over timeline operation is made in commentary video editing with chat-to-edit.
Sparki sits in that last camp: upload the footage you already recorded, describe the edit the way you would brief an editor, and refine the draft across conversation rounds. The boundary stays the one drawn throughout this article — the agent drafts the mechanical pass, you keep the judgment that makes a talking-head video worth watching. If that division of labor fits how you work, Sparki.io is where to try it.
https://sparki.io/blog/talking-head-editing-agent